 Rapid-MLX |
Issue #5 |
|
|
NOV 12–13 · SAN FRANCISCO
|
SGLang Summit has no Mac talk.
So we’re bringing the Mac.
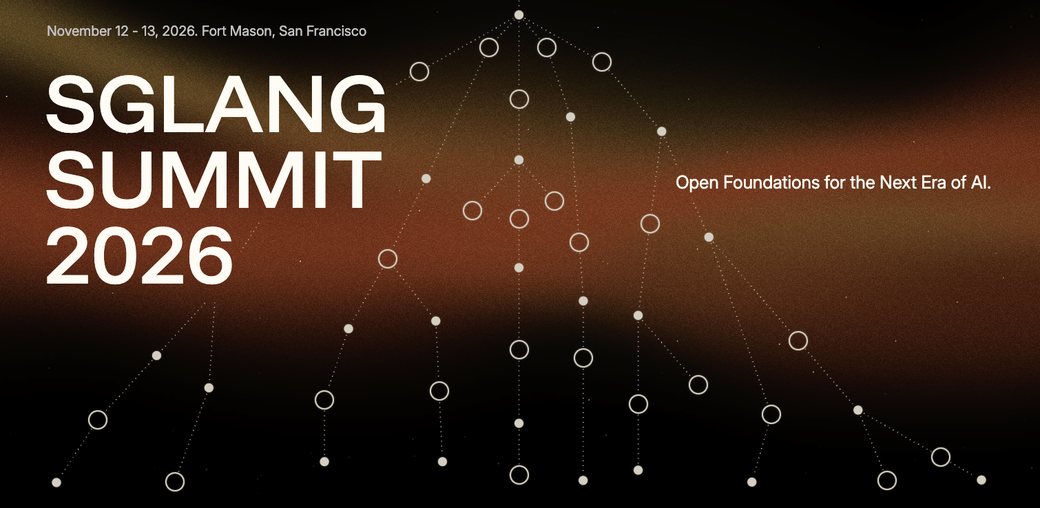
SGLang Summit 2026 · Nov 12–13 · Fort Mason Center, San Francisco
Two days on open AI infrastructure: GPUs, TPUs, serving at scale. Not one session about the computer most people there carry in their bag. So the whole Rapid-MLX team is coming, with MacBooks running open models.
Going? Bring your Mac. Give us two minutes and you’ll walk away with a model running on it and your coding agent connected, no cloud bill attached. Or just come and talk shop.
Find the cheetah: Rapid-MLX is a community sponsor
Not in San Francisco? Here’s what your Mac can do now that it couldn’t two weeks ago.
|
|
01 / LOCAL VIDEO
Make a short film on your desk
No cloud credits, no upload, no queue. Rapid-MLX 1.0.2 added Pika H3 Flex next to MiniMax H3, so the Video tab now makes clips with a matching soundtrack. All three of these came out of one Mac:
 5-second clip with sound · watch → |
 57-second short 10 shots · watch → |
 98-second story with sound · watch → |
MiniMax H3 needs 160 GB of memory or more, and Pika H3 Flex 192 GB. On a smaller Mac, LTX and Wan make video too.
|
|
02 / ANY HUGGING FACE MODEL
Saw a new model this morning? Run it today.
New open models land on Hugging Face every day, usually before anyone converts them for Mac. With Rapid-MLX 1.0.2 you don’t wait: paste the link. When Nous Research released Arete-27B, we ran it from its Hugging Face link the same day, in full precision. Watch →
Will it run on my Mac?
rapid-mlx pull <link> --check
It answers before downloading anything. In Desktop, paste the link into model search.
1.0.2 also makes the first run quicker (a 1.6 GB starter model instead of 3 GB) and frees memory when you step away, while apps connected to your Mac keep working. Everything in 1.0.2 → |
|
03 / M5 ULTRA
What a 512 GB M5 Ultra does with local AI
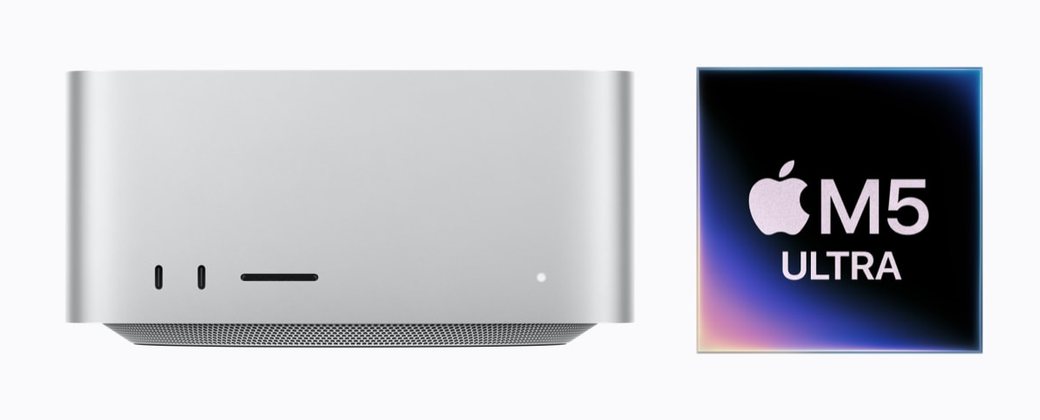
Mac Studio with M5 Ultra · image: Apple
Apple’s new top Mac is hard to find, so we asked the community. @ApacheAE ran our benchmark on one with 512 GB, the first on the board. Qwen3.6 35B writes a 500-token answer in under two seconds:
Qwen3.6 35B
4-bit · 21 GB of memory | 276 tok/s |
Qwen3.5 9B
4-bit | 228 tok/s |
Qwen3.8 27B
4-bit · 18 GB of memory | 105 tok/s |
Rapid-MLX 1.0.2 · tokens per second while answering a 512-token prompt · MTP on · see every runNo Ultra? You’re still fast. On a 36 GB M5 Max, Qwen3.6 35B wrote a playable game from one prompt in 18.5 seconds. Watch it in real time →
|
|
04 / LOCAL SPEECH
Transcribe a meeting without sending it anywhere
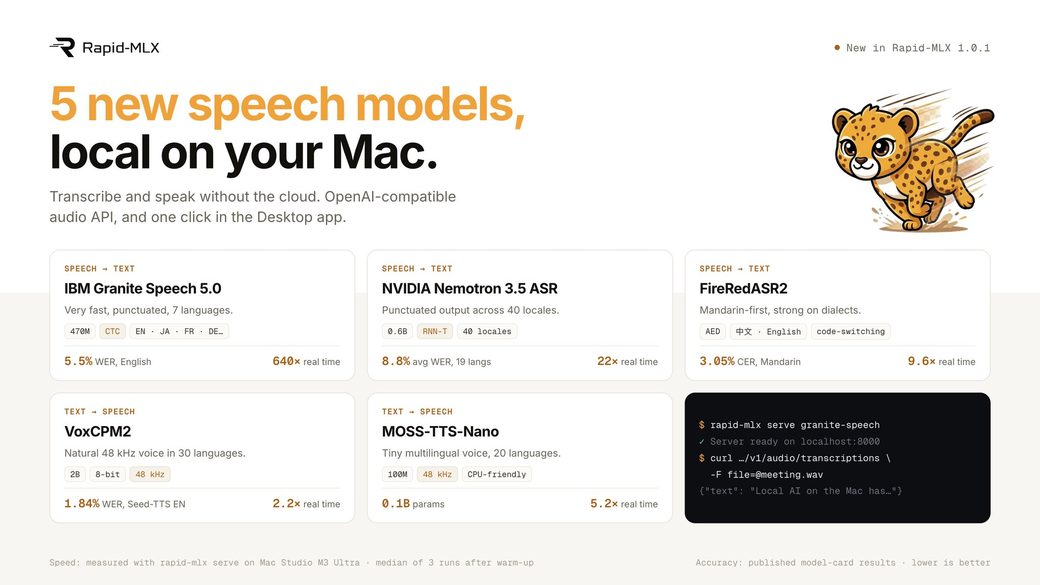
New in Rapid-MLX 1.0.1
Calls, interviews and voice notes stay on your Mac. IBM Granite Speech 5.0 turned 30 seconds of audio into text in 0.05 s on an M3 Ultra. NVIDIA Nemotron 3.5 ASR handles 40 languages and regions, and FireRedASR2 is tuned for Mandarin. To talk back, try VoxCPM2 or MOSS-TTS-Nano. Any app that speaks the OpenAI audio API can use them.
|
|
05 / BEFORE YOU UPGRADE
Rapid-MLX now needs Python 3.12
Installed with pip, uv or pipx on Python 3.10 or 3.11? Upgrading looks like it worked but keeps you on 1.0.0. Rerun the installer instead; it keeps your settings and models:
Rerun the installer
curl -fsSL https://rapidmlx.com/install.sh | bash
Using Desktop or Homebrew? Nothing to do.
|
|
06 / THE COMMUNITY
Does your Mac beat these numbers?
Every speed above comes from someone running the same test on their own Mac. In twelve days you added 272 runs and more than doubled the models on the board.
Put your Mac on the board
rapid-mlx benchmark run qwen3.6-35b
rapid-mlx benchmark share <run-id>
Nothing leaves your Mac until you share it.
Build with your AI. Pull requests written with Claude Code, Codex, Cursor or a local model are welcome; point your agent at AGENTS.md to start. And TokenRace by ernext now includes Rapid-MLX, if you want to time local servers on your own hardware.
Thank you to @ApacheAE for the first M5 Ultra runs, and to @Vinyo3d, @saizai, @soarkit, @abibire, @Korayem, @swf1996120 and @mrl-agent for the bug reports and fixes in these releases.
|
|
07 / COMMUNITY HIGHLIGHTS
What people are building on Rapid-MLX
A coding assistant for health research. ruralpeds/mlx-code-assistant is a small desktop app that drives a local model through a 26-phase build plan for a biostatistics library in Rust. It starts and stops the Rapid-MLX server, runs each phase with one click, and retries when tests fail. The code and the model never leave the Mac.
A 1B model that reads emotions. mauropm/emotions-local-llm is a Go harness that asks LFM2.5 1B (4-bit), served by Rapid-MLX on a 16 GB Mac mini M4, whether a sentence is positive or negative. It scores 1,000 samples from the public dair-ai/emotion dataset with a fixed seed, so anyone can rerun it.
Built something with Rapid-MLX? Reply to this email and it could be in the next issue.
|
|
Everything above runs on the Mac you already own.
Download for Mac →
Free · open source · macOS 14+ · Apple Silicon · no account
already installed? rapid-mlx upgrade
|
|
|
Ran something on your Mac that beat our numbers?
Share it. We'd love to see it on the board.
|
Rapid-MLX · Run great AI locally on Apple Silicon · rapidmlx.com
|