 Rapid-MLX |
Issue #1 |
|
Qwen3.8-Flash-Next runs on your Mac 🚀
The hottest model of the week — Qwen's brand-new 125B flagship — quantized to 4-bit MLX by our team, free on Hugging Face, and served natively by Rapid-MLX 0.13.1. Sub-second replies, dictation + chat side by side. 100% on-device. 100% MLX.
rapid-mlx serve qwen3.8-flash-next-4bit
Experimental · Apache 2.0 · ~104 GB in use — we recommend a 192 GB Mac
Also in our first newsletter: a month of releases in one note — a Mac app born and grown, 40 new models, and speed you can measure.
| 232 models |
|
100% on-device |
|
Apache 2.0 |
|
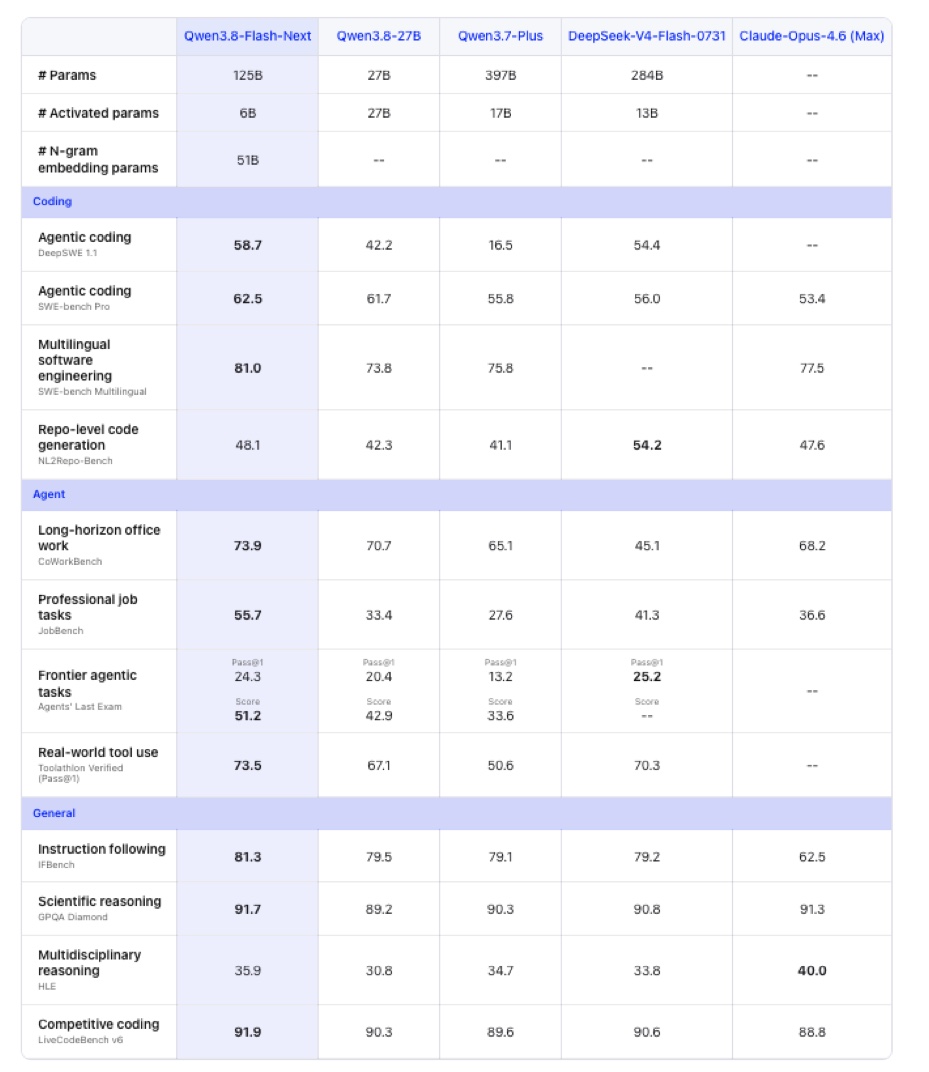
6B active parameters, frontier-class scores — Qwen's published benchmarks. Source → |
|
We quantized it — then measured it
125B parameters in ~104 GB of unified memory. On a Mac Studio: 25.7 tok/s, first token in 0.38 s, and still 19.7 tok/s with a 32K-token prompt. On the same harness as the dense Qwen3.8-27B-4bit, quality holds.
|
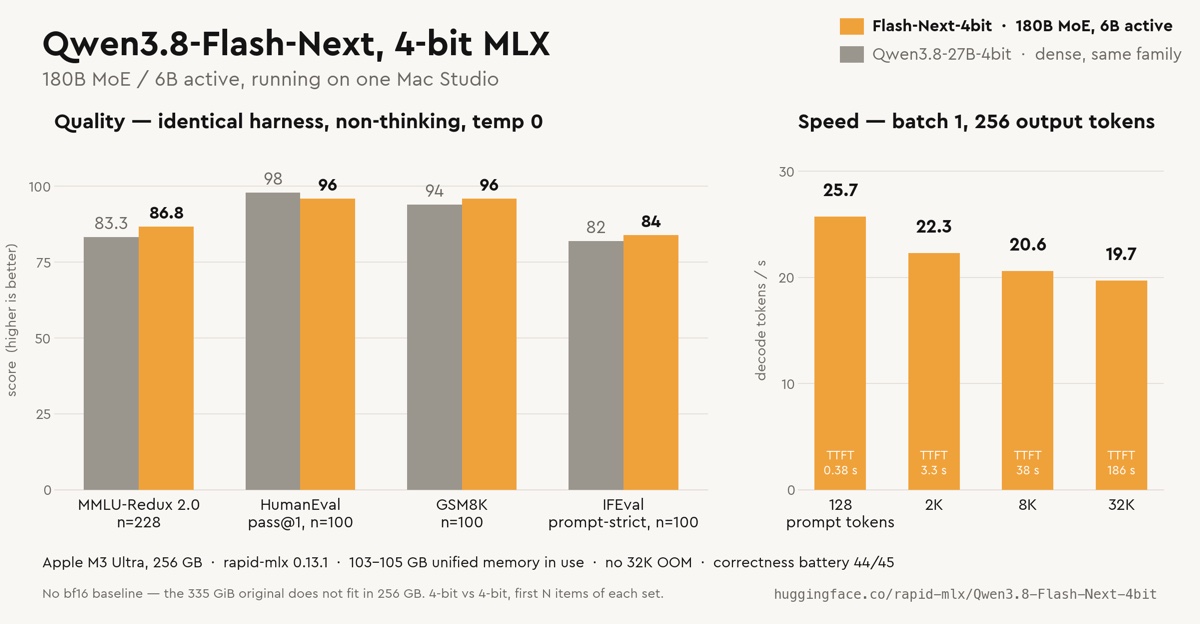
Our 4-bit build vs its dense sibling, measured on an Apple M3 Ultra.
|
44 of 45 on our correctness battery — tool calls on both API routes, JSON schema, needle-in-a-haystack at 8K and 32K, thinking mode. The recipe keeps the MoE routing gates at 8-bit, where quantization does the most damage.
No bf16 baseline: the 335 GiB original does not fit in a 256 GB Mac, so these are 4-bit vs 4-bit. 128 GB untested.
|
|

|
|
Download for Mac →
Free · macOS 14+ · Apple Silicon · updates itself
|
|
or from the terminal
curl -fsSL https://rapidmlx.com/install.sh | bash
|
|
01
The Mac app grew up fast
Born August 3 — open source, same engine underneath. Three weeks later it can:
Dictate anywhere.
Tap right Option — words land at your cursor in any app. Your dictated words stay on your Mac.
Speak back.
Recordings become text, text becomes speech, in a voice you pick — all local.
See and draw.
Chat reads images, PDFs and CSVs; the Images tab paints and refines on your Mac.
Look things up.
Web search out of the box — no account, no API key. MCP tools included.
Keep every answer.
Regenerations stay as switchable branches — step through them under the bubble.
Set itself up.
Model picks measured to your RAM, and signed background updates.
|
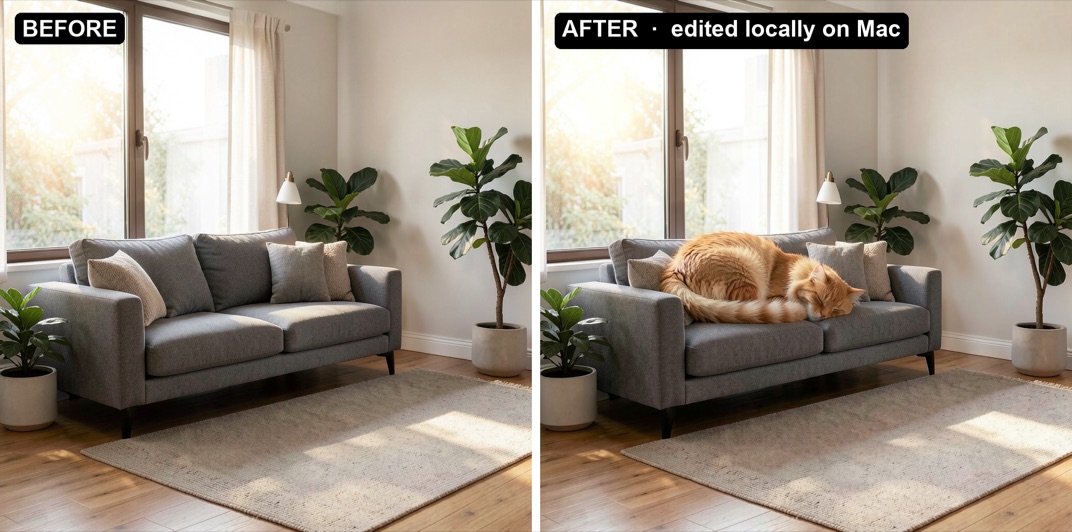
Add a cat to your sofa — generated and edited entirely on a Mac.
|
|
02
New models — 191 → 232 in a month
Qwen3.8-Flash-Next NEW
Qwen's newest 125B MoE, quantized to 4-bit MLX by us — weights on Hugging Face.
|
Ornith-1.5
New MIT-licensed family: 9B dense + 35B MoE, tools working day one.
|
DeepSeek V4 Flash
The most capable open-weights model in the catalog.
|
Qwen3.8-27B
Served day-0, text and vision — and our mixed-precision 3.5-bit build just passed 1,000 downloads on Hugging Face.
|
Muse Glimmer 30B
Served natively the same week Meta released it.
|
Ling-3.0-tiny
A 131K-context reasoner that fits an 8 GB Mac — the first MLX conversion anywhere.
|
…and 35 more
Video, image and music generation included — all mirrored on our CDN for fast pulls.
|
|
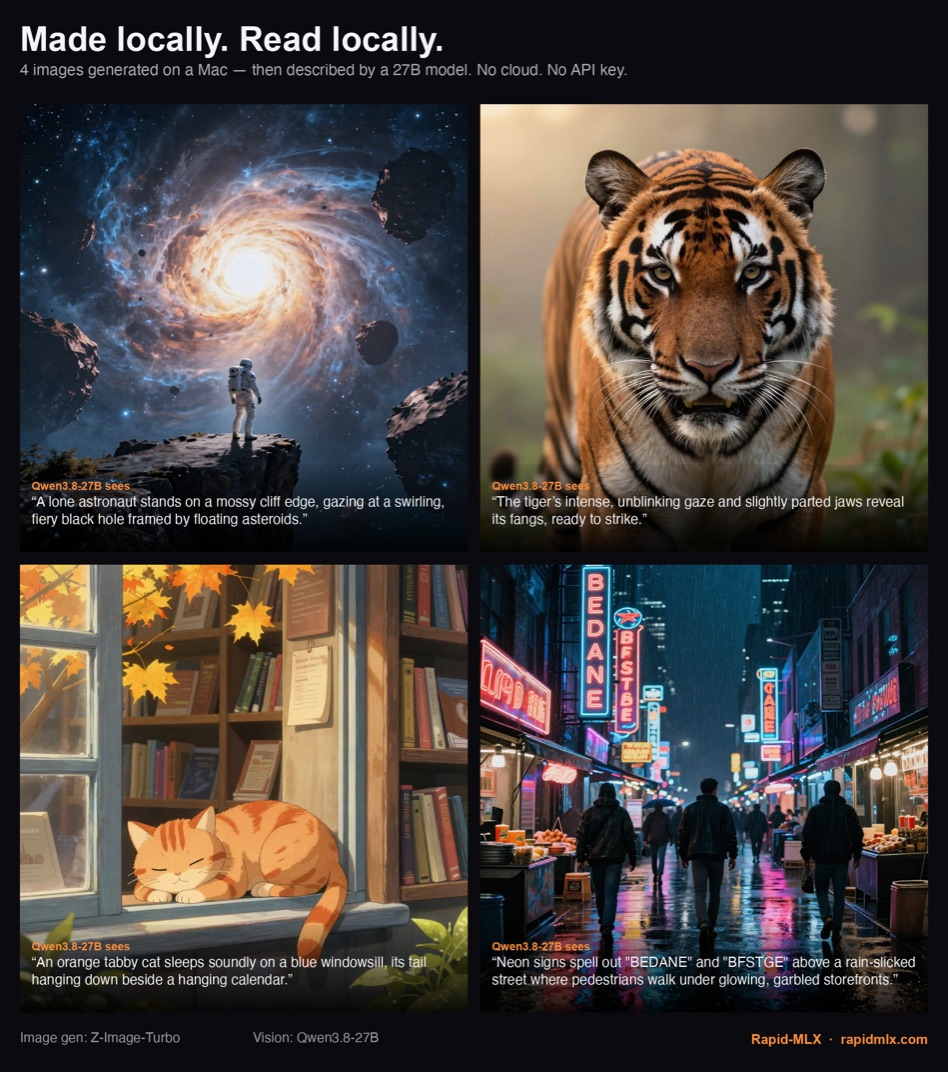
Made locally, read locally: generated by Z-Image-Turbo, described by Qwen3.8-27B.
|
|
03
Your Mac learned audio and video
Video generation.
Wan, CogVideoX and LTX render MP4s on your own machine, through an OpenAI-style API.
Voice cloning, four ways.
Or describe a voice in a sentence — and a seed brings the same narrator back every time.
Precise transcription.
Word-level timestamps, per-character alignment for captions, fast CJK recognition.
Text-to-music.
Stable Audio 3, served locally.
|
|
04
Faster, measured
|
20×
faster second-turn replies
4.20 s → 0.21 s to first token
|
|
81×
faster warm starts
on DeepSeek V4, byte-identical
|
| |
|
+41%
throughput under load
190 → 268 tok/s at 8 streams
|
|
+23%
with multi-token prediction
same output, same sha256
|
All measured on an Apple M3 Ultra. Details in the changelogs.
|
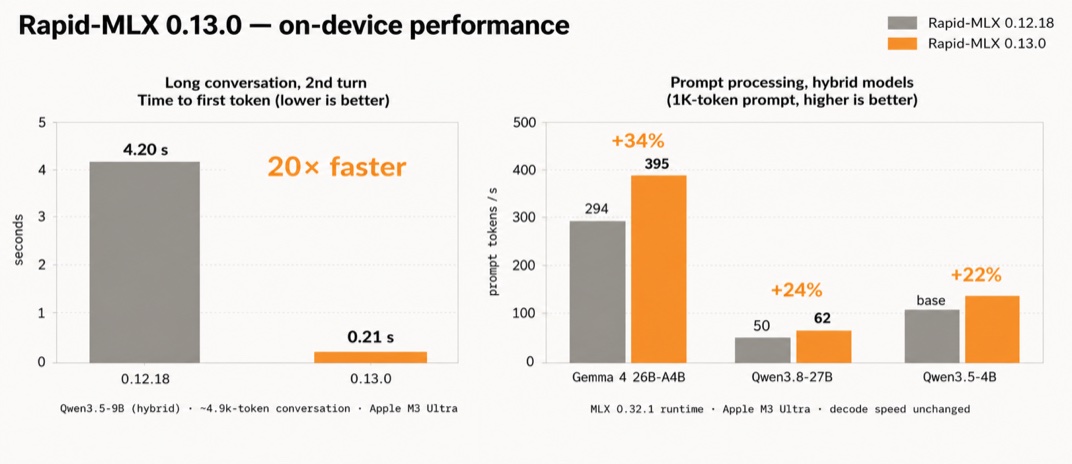
0.13.0 vs 0.12.18 — and hybrid prompt processing gains another +22–34%.
|
|
See measured speeds for your chip →
|
|
05
For coding agents
Tool calling got a truth pass.
What the model means to call is what runs — and a malformed call now recovers instead of dropping.
Five agents, tested every release.
Claude Code, Codex, Hermes, Aider and DeepSeek Harness — each a one-command setup, each run before we ship.
Honest surfaces.
Agents see the context window your Mac can actually serve, and models are integrity-checked before loading.
|
That's issue #1. Everything above runs on the Mac you already own —
no account, no cloud, free. See you next release.
|